Knowledge Spaces vs. Traditional Document Portals
Many document platforms now offer AI assistants. Evaluate whether the existing platform meets the task before adding another layer.
 Knowledge Spaces
Applications
Governance
Delivery
Advisory
Industries
Government and Teaming
Company
Contact
Contact
Scope a Six-Week Pilot
Every enterprise has the same hidden problem: critical knowledge is buried in documents that nobody can find. Reports sit in shared drives, policies live in outdated wikis, and institutional expertise disappears when employees leave. Traditional keyword search was supposed to solve this, but anyone who has tried to find a specific clause in a 200-page contract knows how inadequate it really is.
AI-powered document search represents a fundamental shift in how organizations retrieve and use information. Instead of matching keywords, these systems understand meaning. They grasp context, recognize relationships between concepts, and deliver answers, not just links to documents. For enterprises drowning in unstructured data, this is the difference between having information and actually being able to use it.
Keyword-based search engines work well when you know exactly what you are looking for and can guess the precise words the author used. But enterprise knowledge does not work that way. A procurement officer searching for “vendor risk assessment” might miss a critical document titled “supplier evaluation framework” because the terminology does not match, even though the content is exactly what they need.
The problem compounds at scale. A mid-size federal agency might have millions of documents across dozens of repositories, each using different naming conventions, formats, and classification schemes. Traditional search returns hundreds of results, forcing analysts to spend hours sifting through irrelevant matches. Studies consistently show that knowledge workers spend 20 to 30 percent of their time just searching for information, time that could be spent on analysis, decision-making, and mission-critical work.
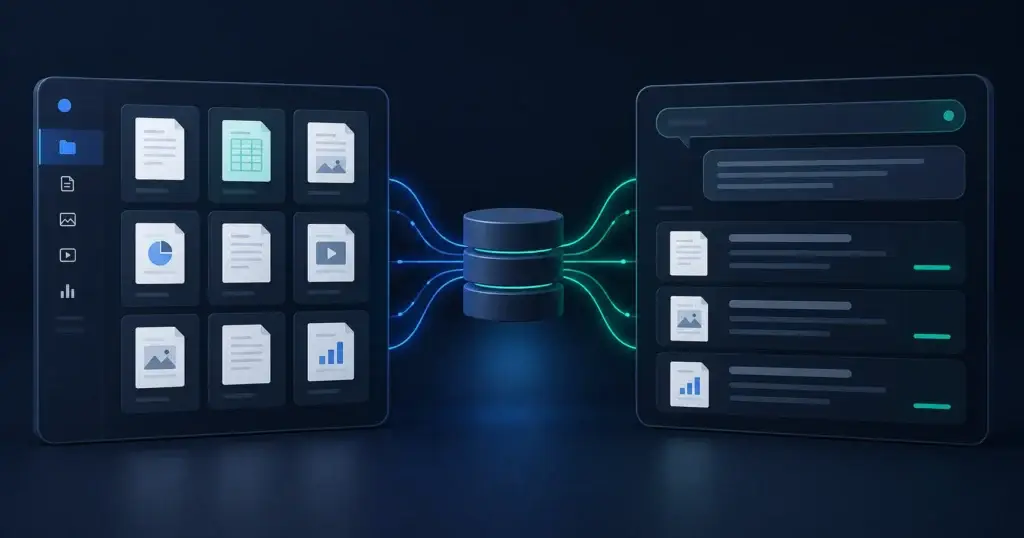
Modern AI-powered search systems use a technique called retrieval-augmented generation (RAG) to bridge the gap between what users ask and what documents contain. The process starts with converting documents into mathematical representations called embeddings, essentially translating text into a language that machines can compare and reason about.
When a user asks a question in plain English, the system converts that query into the same mathematical space and finds the most semantically similar content across the entire document repository. The key difference is that this matching happens at the meaning level, not the keyword level. A search for “employee termination procedures” will surface documents about “offboarding protocols” or “separation policies” because the AI understands these concepts are related.
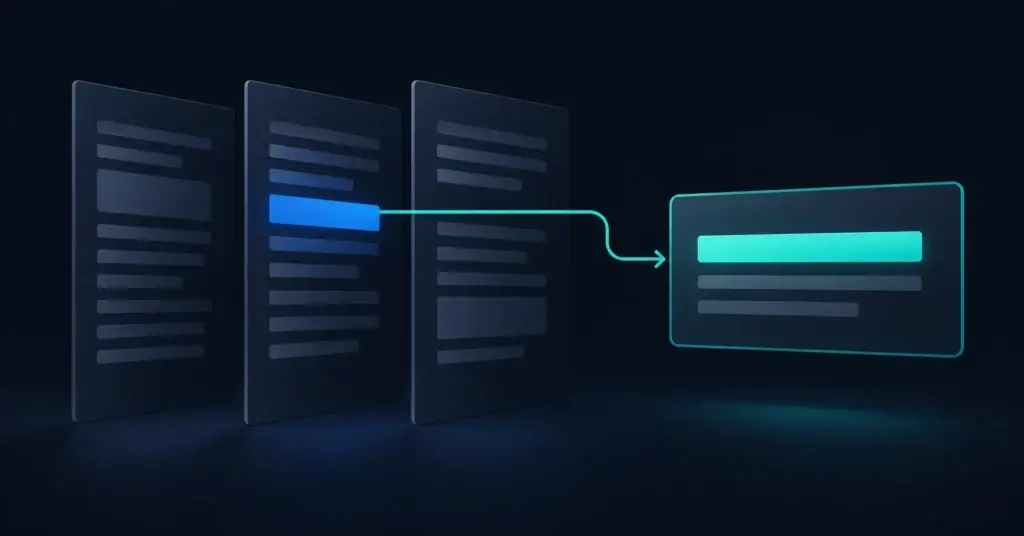
The retrieval-augmented generation layer then takes the most relevant document passages and uses a large language model to synthesize a coherent answer, complete with citations pointing back to the source material. Users get a direct answer to their question plus the ability to verify it against the original documents. This is exactly the approach that powers platforms like Knowledge Spaces, which transforms static document repositories into interactive, queryable knowledge bases.
Not all AI search implementations are created equal. When evaluating solutions for enterprise deployment, several capabilities separate production-ready platforms from proof-of-concept demos. First, multi-format ingestion is essential. Your system needs to handle PDFs, Word documents, spreadsheets, presentations, emails, and even scanned images with OCR. If it only works with clean text files, it will miss most of your knowledge base.
Second, permission-aware search is non-negotiable for enterprise environments. When an analyst queries the system, they should only see results from documents they are authorized to access. This is particularly critical in government and regulated industries where information compartmentalization is a legal requirement, not just a preference. Platforms designed for government environments build these access controls into the foundation rather than bolting them on as an afterthought.
Third, source attribution and traceability must be built in from the ground up. Every AI-generated answer needs to link back to specific passages in specific documents. This builds trust, and in regulated environments the ability to trace a conclusion back to its authoritative source is an audit requirement. Without proper attribution, AI search becomes a liability rather than an asset.
Successful enterprise AI search deployments share common patterns. They start with a focused use case rather than trying to index everything at once. A legal team searching contracts, a compliance group monitoring regulations, or a help desk answering employee questions, each of these represents a bounded problem where the value is clear and measurable.
The systems integration work is often the hardest part. Connecting AI search to existing document management systems, respecting existing access controls, and fitting into established workflows requires careful engineering. Organizations that treat this as a plug-and-play technology purchase rather than an integration project consistently underestimate the effort required.
Data quality matters more than model sophistication. A well-organized document repository with clear metadata will deliver better search results with a basic RAG implementation than a poorly organized mess will with the most advanced AI. Before investing in AI search technology, invest time in cleaning up your document collection, removing duplicates, updating outdated materials, and establishing consistent naming conventions.
The most meaningful metric for AI-powered document search is time-to-answer: how long it takes a knowledge worker to go from having a question to having a verified, actionable answer. In organizations that track this, AI search typically reduces time-to-answer by 60 to 80 percent compared to manual search methods.
Other indicators worth tracking include search abandonment rate (how often users give up without finding what they need), answer accuracy (verified through periodic human review), and adoption rate across the organization. If people are not using the system, it does not matter how sophisticated the technology is.
The strategic value goes beyond productivity gains. Organizations with effective AI search capabilities make better decisions because they have better access to their own institutional knowledge. They onboard new employees faster because tribal knowledge becomes searchable. And they reduce risk because compliance-critical information is findable rather than buried in forgotten folders.
For organizations ready to move beyond keyword search, the path forward starts with understanding your current knowledge sources. Audit where your documents live, how they are organized, and what questions your teams ask most frequently. These high-frequency questions represent your best starting point because the value of AI search will be immediately obvious.
From there, select a platform that aligns with your security requirements, integrates with your existing infrastructure, and can grow with your needs. The Knowledge Spaces platform was designed specifically for this type of enterprise deployment, with particular attention to the security and compliance requirements that government and regulated-industry organizations demand.
The technology is mature enough for production use today. The question is no longer whether AI document search works, but how quickly your organization can deploy it and start converting buried knowledge into competitive advantage.
Many document platforms now offer AI assistants. Evaluate whether the existing platform meets the task before adding another layer.
A citation should let the reader inspect the passage that supports a claim.
Fine-tuning teaches a model how to behave, not what is true.
Most weeks I send one short read on enterprise AI: what’s working in real deployments, what’s not, and what I’d do in your seat.
Jamie Thompson, Founder and CEO