Knowledge Spaces vs. Traditional Document Portals
Many document platforms now offer AI assistants. Evaluate whether the existing platform meets the task before adding another layer.
 Knowledge Spaces
Applications
Governance
Delivery
Advisory
Industries
Government and Teaming
Company
Contact
Contact
Scope a Six-Week Pilot
If you’re building a Retrieval-Augmented Generation (RAG) system, you’ll spend more time thinking about your vector database than you expect. The Sprinklenet team has been through this decision multiple times while building Knowledge Spaces, our enterprise AI platform, and ClearCast, our multilingual intelligence tool.
The vector database is the backbone of your retrieval pipeline. Get it wrong and your AI gives bad answers, no matter how good your LLM is. Get it right and retrieval feels invisible, which is exactly how it should feel.
No vendor marketing here. Just practical observations from building and running these systems in production.
Before comparing options, let’s be precise about the job.
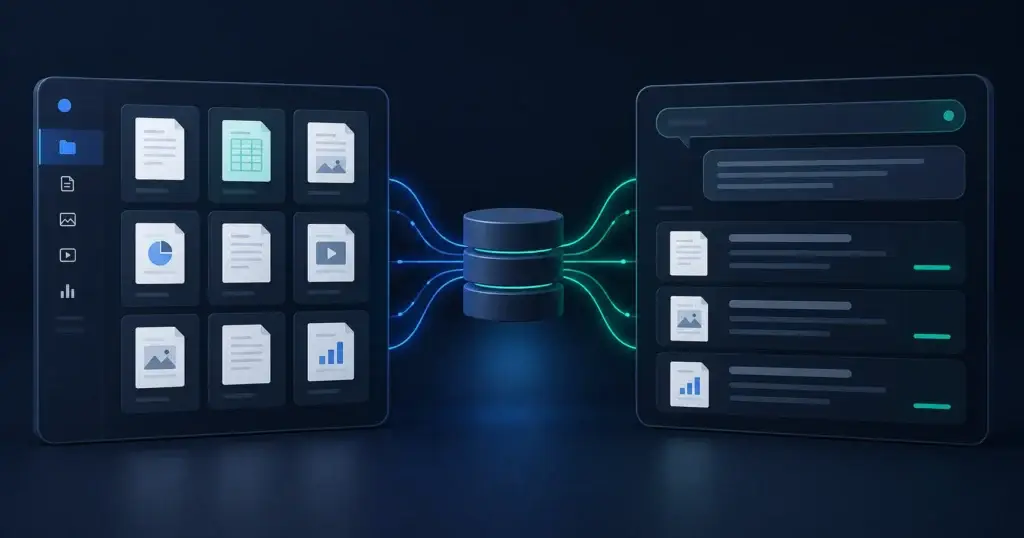
A vector database stores high-dimensional numerical representations (embeddings) of your content and enables fast similarity search across those embeddings. When a user asks a question, your system converts that question into an embedding using the same model that embedded your documents, then queries the vector database for the most similar document chunks.
The quality of your retrieval depends on three things: your embedding model, your chunking strategy, and your vector database’s ability to return accurate results quickly. The vector database handles that third piece.
What makes vector databases different from traditional databases is the search algorithm. You’re not matching exact values. You’re finding the nearest neighbors in a high-dimensional space, typically using algorithms like HNSW (Hierarchical Navigable Small World) or IVF (Inverted File Index). The tradeoffs between these algorithms, and how each database implements them, drive most of the practical differences you’ll encounter.
The team has worked meaningfully with four vector databases. Here is what that experience has revealed.
Knowledge Spaces runs its primary retrieval index on a fully managed vector database, which handles scaling, replication, and index optimization without operational overhead.
What works well:
What to watch for:
Qdrant is what we use in ClearCast for multilingual semantic search. It’s an open-source vector database written in Rust, and it offers a different set of tradeoffs than Pinecone.
What works well:
What to watch for:
pgvector is a PostgreSQL extension that adds vector similarity search to your existing Postgres database. It’s not a standalone vector database. It’s vector search bolted onto the database you probably already have.
What works well:
What to watch for:
Practical take: pgvector is the right choice more often than the vector database vendors want you to believe. If your dataset is under 5 million vectors, your query volume is moderate, and you’re already running Postgres, pgvector eliminates an entire category of operational complexity. Start here unless you have a specific reason not to.
Weaviate is an open-source vector database with a strong focus on hybrid search (combining vector and keyword search) and a GraphQL-based query API.
What works well:
What to watch for:
After building with all four, here is a practical decision framework.
Choose Pinecone if: you want zero operational overhead, your team is small, your budget can absorb the cost, and you don’t have air-gap or data sovereignty requirements. It’s the fastest path to production-quality retrieval.
Choose Qdrant if: you need self-hosting capability, you want strong performance with lower cost, and your team can handle infrastructure management. Best fit for government deployments and organizations with strict data residency requirements.
Choose pgvector if: your dataset is moderate (under 5 million vectors), you’re already on PostgreSQL, and you want to minimize architectural complexity. The right default choice for most early-stage RAG systems.
Choose Weaviate if: hybrid search quality is your primary concern, you need native multi-tenancy, and you’re comfortable with a heavier operational footprint.
Here is what matters most. Your vector database choice matters less than three other decisions in your RAG pipeline.
Chunking strategy. How you split documents into chunks has a bigger impact on retrieval quality than which database stores those chunks. Chunk size, overlap, boundary detection (splitting on paragraphs vs. sentences vs. token counts), and metadata preservation all affect retrieval precision. We’ve spent more engineering time on chunking in Knowledge Spaces than on vector database integration.
Embedding model selection. The embedding model determines the quality of your vector representations. A great vector database can’t fix bad embeddings. Test multiple embedding models on your specific data. We use different embedding approaches in Knowledge Spaces (Pinecone’s built-in embedding pipeline) and ClearCast (BGE-M3 for multilingual coverage) because the data characteristics are completely different.
Retrieval evaluation. Most teams never systematically measure their retrieval quality. They ship a RAG system and hope it works. Build an evaluation set of queries with known relevant documents. Measure recall and precision. Track these metrics over time. A 10% improvement in retrieval recall will do more for your system’s output quality than switching vector databases.
The vector database is infrastructure. Important infrastructure, but infrastructure. Get the fundamentals right, pick the option that fits your operational reality, and spend your engineering energy on the problems that actually drive output quality.
Building a RAG system for enterprise or government?
Knowledge Spaces handles model routing, vector retrieval, guardrails, and audit logging in a single managed platform.
Many document platforms now offer AI assistants. Evaluate whether the existing platform meets the task before adding another layer.
A citation should let the reader inspect the passage that supports a claim.
Fine-tuning teaches a model how to behave, not what is true.
Most weeks I send one short read on enterprise AI: what’s working in real deployments, what’s not, and what I’d do in your seat.
Jamie Thompson, Founder and CEO