Knowledge Spaces vs. Traditional Document Portals
Many document platforms now offer AI assistants. Evaluate whether the existing platform meets the task before adding another layer.
 Knowledge Spaces
Applications
Governance
Delivery
Advisory
Industries
Government and Teaming
Company
Contact
Contact
Scope a Six-Week Pilot
Ask a new enterprise knowledge assistant a policy question and watch which document it answers from. Often it is the wrong one: a stale draft on a shared drive instead of the approved version, or a wiki page summarizing the rule instead of the rule itself. The model did nothing wrong. It summarized what retrieval handed it, and retrieval handed it the loudest document, not the authoritative one.
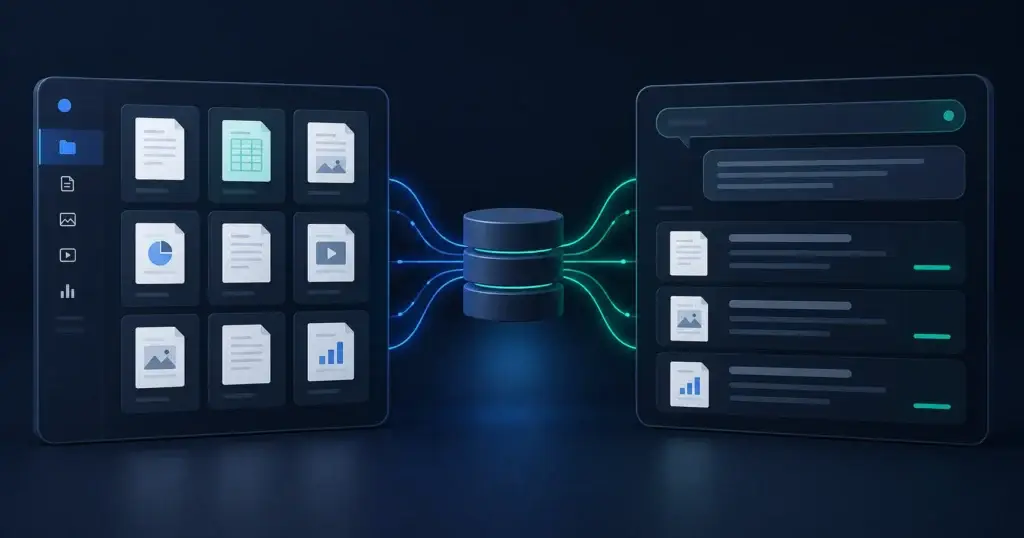
That is why the retrieval layer is the product foundation, not a background utility. Most of what determines whether people can trust an operational AI system is decided before the model sees a token: which sources get indexed, which version wins, who sees what, and how withdrawn content leaves the index.
Operational knowledge rarely lives in one place. The same travel policy exists as an approved PDF in a document system, an intranet summary, three drafts in a shared folder, and a screenshot in a ticket thread. Someone has to decide which one is authoritative, and that call belongs to the business owner of the content, not the engineer wiring the connector.
The practical move is a source inventory: for each document class, name the system of record, the human owner, the refresh cadence, and the audience. Unglamorous, but it pays back more than any ranking tweak, because a pipeline that indexes everything treats the abandoned draft and the approved policy as equals.
A good retrieval layer is also easy to explain: which systems feed it, why an answer cited a given document, and who gets paged when a connector breaks.
The most common security mistake in this work is indexing everything into one store and filtering results in the application layer. That fails twice: post-retrieval filtering leaks information through ranking behavior and snippets, and it breaks the moment a second application shares the index. Permission filtering belongs inside the retrieval query, using access metadata carried from the source system, and it has to be testable: ask the same question as users with different entitlements and verify the restricted document never appears.
Document lifecycle deserves the same discipline. When legal withdraws a document from the system of record, the removal has to propagate to the index and its embeddings on a defined schedule. An assistant that keeps citing a withdrawn policy is not a quality problem; it is a compliance incident.
The pattern that survives production is narrow and staged: one workflow, one corpus, one user group. Prove the data path end to end, connector to citation, before adding a second source. In practice that is a six-week path to pilot use: early weeks on the source inventory and connector plumbing, the middle on permission mapping and a fixed evaluation set of real questions with known correct sources, the final stretch on operations: index rebuilds, sync alerts, and a rollback plan.
Evaluate retrieval on its own before judging answers. If the right passage never reaches the candidate set, no prompt work will rescue the response; if it does, most generation problems become tractable. A fixed question set with graded source relevance tells you more than a demo transcript.
These are not bureaucratic gates. They are the difference between a system the security team approves once and one re-reviewed every quarter because nobody can show how it behaves.
What makes these failures expensive is when they surface: invisible in a demo on a curated folder, obvious in week five when real users with real entitlements ask what the demo never covered.
A team that answers these in specifics, naming systems and owners, is ready to build. One that cannot should spend two weeks on the source inventory first; that is far cheaper before launch than after.
Sprinklenet built Knowledge Spaces on this premise: governed retrieval over enterprise knowledge is worth engineering carefully, designed for enterprise and government-grade requirements from the start. The platform carries the control plane described here: source connectors, permission-aware retrieval, and citation behavior. That lets a delivery team spend its six weeks on the workflow instead of the plumbing.
Explore Knowledge Spaces, review our AI services, or contact Sprinklenet to talk through a retrieval problem you are working on.
Many document platforms now offer AI assistants. Evaluate whether the existing platform meets the task before adding another layer.
A citation should let the reader inspect the passage that supports a claim.
Fine-tuning teaches a model how to behave, not what is true.
Most weeks I send one short read on enterprise AI: what’s working in real deployments, what’s not, and what I’d do in your seat.
Jamie Thompson, Founder and CEO