Retrieval Evaluation: What to Measure Before Launch
Separate retrieval failures from answer failures.
 Knowledge Spaces
Applications
Governance
Delivery
Advisory
Industries
Government and Teaming
Company
Contact
Contact
Scope a Six-Week Pilot
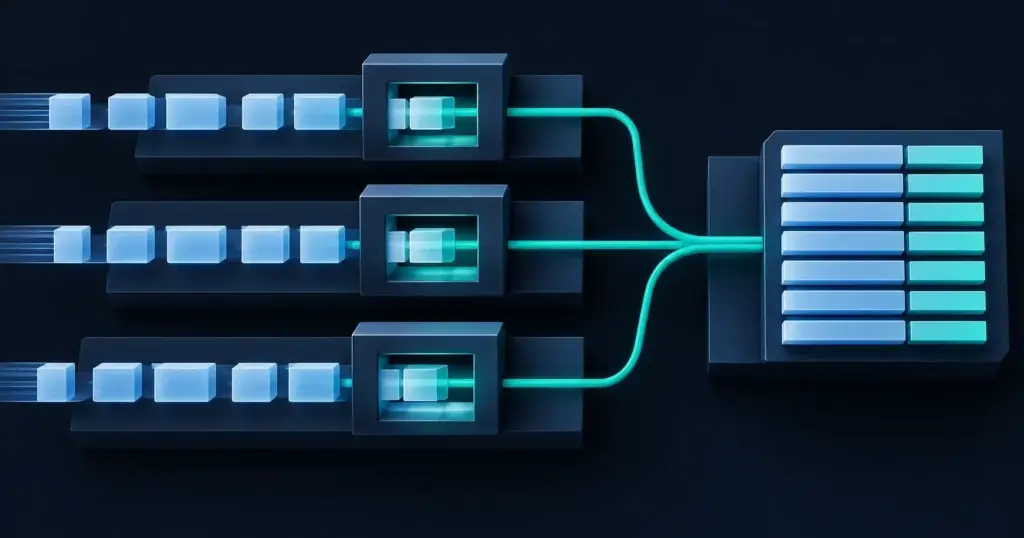
Before building the index, select a representative document set and test extraction, source identifiers, access rules, updates, and removals. Record failures by document type so the team can fix the pipeline before treating answer quality as a model problem.
Record source owner, effective date, allowed users, update method, and intended questions. Exclude superseded or unapproved copies from the initial serving collection.
Test headings, tables, scanned pages, footnotes, and policy exceptions before bulk ingestion. Keep the original record and enough location metadata to inspect extraction failures.
A document can appear successfully processed while losing the relationship that makes its content meaningful. In a hypothetical policy table, the text extractor might retain every amount and label but separate the values from the conditions they describe. A search result containing the correct words could then support the wrong answer. Compare selected extracted passages with the original page, especially where tables, footnotes, and exceptions carry the rule. Keep extraction defects separate from retrieval tuning so the team does not try to repair damaged source content by changing the model.
Specify how change signals trigger processing and what happens after a missed update. Test serving-index removal separately from any retention duty for the original record.
Example: Withdraw a test policy, replace it with a new version, and confirm that the assistant no longer cites the withdrawn version for current guidance.
Maintain a small task set tied to expected source versions and passages. Inspect ingestion and retrieval evidence before attributing every weak answer to the model.
Discuss the implementation scope with Sprinklenet. A useful starting point: a source-readiness and update-path review before RAG implementation.
The recommendations above are Sprinklenet’s practical guidance. Technical context: Microsoft Document Chunking Guidance, Google Drive Change Tracking, Microsoft Graph Delta Queries.
Separate retrieval failures from answer failures.
A citation should let the reader inspect the passage that supports a claim.
Pilot with a bounded collection of approved folders.
Most weeks I send one short read on enterprise AI: what’s working in real deployments, what’s not, and what I’d do in your seat.
Jamie Thompson, Founder and CEO