Retrieval Evaluation: What to Measure Before Launch
Separate retrieval failures from answer failures.
 Knowledge Spaces
Applications
Governance
Delivery
Advisory
Industries
Government and Teaming
Company
Contact
Contact
Scope a Six-Week Pilot
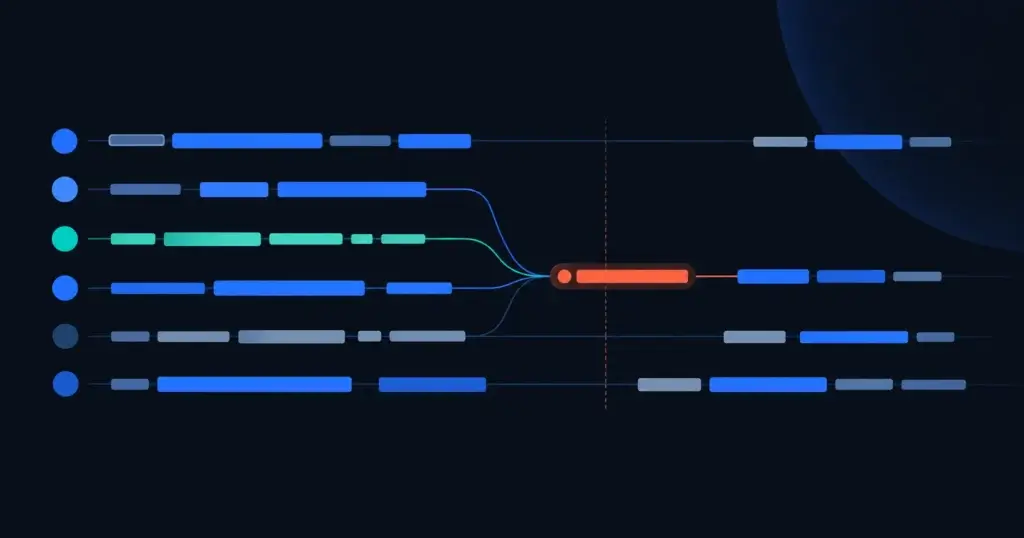
Use an operating dashboard that connects service health to task quality. Track failed imports, response latency, cost per completed task, citation support, and unresolved escalations. Define an owner and response threshold for each measure, and minimize sensitive content in logs.
Track imports, retrieval failures, latency, task completion, and unresolved escalations. Give every metric an owner and a decision or response it supports.
Sample answer support and completeness using representative tasks. Keep failed retrieval, unsupported generation, and outdated source content distinguishable.
Example: A service can return fast responses with successful HTTP status codes while citing a superseded policy. Latency and HTTP success rates would miss the problem.
Collect the smallest useful diagnostic record and control access to it. Decide explicitly whether any prompt or response content is retained, redacted, sampled, or excluded.
Define escalation thresholds for failures and spending, plus who investigates them. Review trends alongside changes in traffic, models, prompts, and source collections before inferring improvement.
A dashboard can improve because the workload became easier, even when the system did not. If users stop asking complex questions after poor experiences, average response time and completion figures may look better while useful adoption declines. Review measures by task type and configuration version, and include failures that led users to seek help elsewhere. The operating decision should be specific: investigate a source, change a workflow, adjust capacity, or revise a release. A chart without an intended response is unlikely to help an executive allocate attention.
Discuss the implementation scope with Sprinklenet. A useful starting point: an operating dashboard and incident-response design tied to a specific AI workflow.
The recommendations above are Sprinklenet’s practical guidance. Technical context: OpenTelemetry Sensitive Data Handling, Microsoft RAG Evaluators.
Separate retrieval failures from answer failures.
Ask the supplier to demonstrate one allowed request, one denied request, a revoked permission, and a failed connector.
Use one entry per concrete failure scenario. Record the affected workflow, consequence, existing control, evidence, owner, and next review date.
Most weeks I send one short read on enterprise AI: what’s working in real deployments, what’s not, and what I’d do in your seat.
Jamie Thompson, Founder and CEO